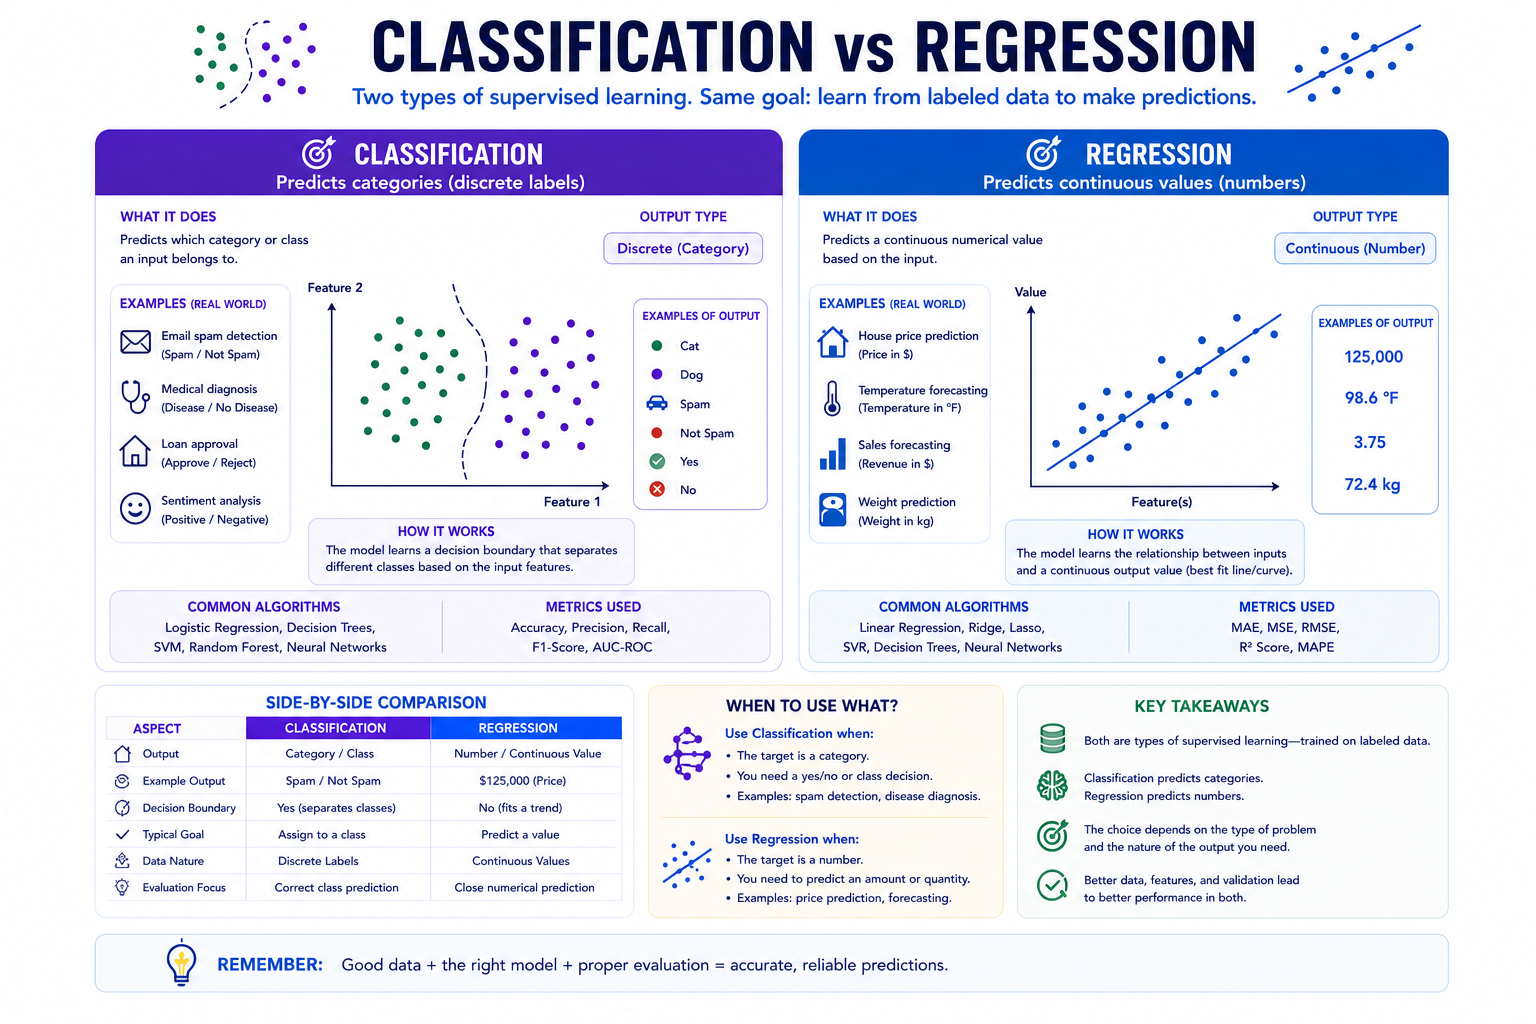
Classification and regression are the two main prediction-task families in supervised learning. Both learn from labeled examples, but they answer different kinds of questions.
- Classification predicts a category or class, such as spam or not spam.
- Regression predicts a continuous numerical value, such as delivery time or energy demand.
The distinction matters because it affects how targets are represented, which models and loss functions are appropriate, how results are evaluated, and how predictions are used.
Last reviewed and updated: August 27, 2026.
Prerequisite: Read Supervised Learning Explained first if labeled data, model training, validation, and testing are new concepts.
Classification vs Regression: The Core Difference
| Question | Classification | Regression |
|---|---|---|
| What does it predict? | A category, class, or label | A continuous numerical value |
| Example output | Spam, not spam | Estimated delivery time: 42 minutes |
| Typical examples | Fraud detection, image categories, sentiment labels | Price estimation, demand forecasting, temperature prediction |
| Common metrics | Accuracy, precision, recall, F1, ROC-AUC | MAE, MSE, RMSE, R² |
| Main output form | Class label, often derived from class probabilities and a threshold | Number on a continuous scale |
What Is Classification?
Classification assigns an example to one or more predefined categories. The model usually produces a score or probability for each possible class, and the system converts those scores into a prediction.
Examples include:
- Classifying an email as spam or not spam.
- Predicting whether a transaction is fraudulent.
- Assigning a support request to a routing category.
- Identifying the type of object shown in an image.
- Labeling text as positive, neutral, or negative.
Binary, multiclass, and multilabel classification
- Binary classification chooses between two classes, such as approve or reject.
- Multiclass classification chooses one class from three or more possibilities, such as cat, dog, or bird.
- Multilabel classification can assign several labels to one example, such as tagging an article with both machine learning and computer vision.
How classification is evaluated
A useful evaluation must reflect the cost of different mistakes and the balance of classes in the data.
- Accuracy is the share of all predictions that are correct. It can be misleading when one class is rare.
- Precision asks how often positive predictions are actually positive.
- Recall asks how many actual positive examples the model finds.
- F1 balances precision and recall in one score.
- ROC-AUC summarizes ranking performance across classification thresholds, but it should not replace task-specific analysis.
The classification threshold matters. A fraud system, for example, may lower its threshold to catch more suspicious transactions, but that can also increase false alarms. The correct tradeoff depends on risk, cost, and how predictions are reviewed.
What Is Regression?
Regression predicts a continuous numerical value. The target is an amount, measurement, duration, rate, or other quantity rather than a named category. See Linear Regression Explained for a step-by-step example connecting an input, fitted equation, prediction, and residual.
Examples include:
- Estimating the sale price of a house.
- Predicting electricity demand.
- Estimating delivery time.
- Forecasting equipment temperature under known operating conditions.
- Predicting the remaining useful life of a machine component.
A regression output is an estimate, not a guarantee. Real-world outcomes may depend on missing variables, measurement error, changing conditions, and events the model cannot observe. Financial and medical predictions require especially careful validation and should not be presented as certain outcomes.
How regression is evaluated
- Mean absolute error (MAE) measures the average absolute difference between predictions and actual values. It is expressed in the target’s units.
- Mean squared error (MSE) squares errors before averaging, giving larger mistakes more influence.
- Root mean squared error (RMSE) is the square root of MSE and returns the error to the target’s units.
- R² measures how much variation the model explains relative to a baseline. It should be interpreted alongside error metrics and can be negative on evaluation data.
No metric is universally best. MAE may be easier to explain, while RMSE penalizes large errors more heavily. The right choice depends on how errors affect the real task.
The Same Problem Can Be Framed Both Ways
Some problems can be framed as either classification or regression depending on the decision being supported.
- Classification framing: Will this delivery arrive late?
- Regression framing: How many minutes will the delivery take?
- Classification framing: Is this customer likely to leave?
- Regression framing: What is the estimated probability that this customer will leave?
The second customer example illustrates an important detail: many classifiers calculate a probability or score before a threshold converts it into a class label. A numerical intermediate output does not automatically make the task regression. The target and intended decision determine the task type.
Which Algorithms Support Classification or Regression?
| Algorithm family | Classification | Regression |
|---|---|---|
| Linear regression | No | Yes |
| Logistic regression | Yes | No, despite its name |
| Decision trees | Yes | Yes |
| Random forests | Yes | Yes |
| Support vector machines | Yes | Yes, through support vector regression |
| K-nearest neighbors | Yes | Yes |
| Neural networks | Yes | Yes |
Algorithm choice also depends on dataset size, feature types, nonlinear relationships, interpretability needs, latency, available compute, and how the model will be maintained. Start with a reasonable baseline and compare alternatives using validation data.
Explore Decision Trees Explained, Random Forest Explained, Support Vector Machines Explained, K-Nearest Neighbors Explained, and Neural Networks Explained.
How to Choose Between Classification and Regression
- Define the target. Is the required answer a category or a continuous number?
- Define the real decision. Decide how the prediction will be used and what each kind of error costs.
- Inspect the labels. Confirm that targets are accurate, consistent, representative, and available at prediction time.
- Choose evaluation metrics before tuning. Metrics should match the decision rather than merely produce a high score.
- Create training, validation, and test splits. Prevent duplicate entities, future information, or target leakage from crossing splits.
- Compare against a baseline. A complex model should outperform a simple, meaningful reference.
Common Mistakes
- Using accuracy for a highly imbalanced classification problem. A model can appear accurate while missing nearly every rare case.
- Treating probability prediction as regression without considering the target. Class probabilities usually belong to a classification workflow.
- Ignoring the scale of regression errors. An MAE of 10 may be excellent or unacceptable depending on the unit and application.
- Training on information unavailable at prediction time. This creates leakage and unrealistic evaluation results.
- Choosing a metric after seeing the results. This can encourage selection of the metric that makes the model look best rather than the one the task requires.
- Assuming historical patterns will remain stable. Distribution shift can reduce both classification and regression performance after deployment.
Sources and Further Reading
- Google for Developers: Supervised Learning
- Google Machine Learning Crash Course: Classification Metrics
- Google Machine Learning Crash Course: Regression Loss
- Scikit-learn User Guide: Supervised Learning
- NIST Computer Security Resource Center: Machine Learning
Frequently Asked Questions
Is logistic regression classification or regression?
Logistic regression is commonly used for classification. It estimates a probability that can be converted into a class prediction using a threshold.
Can one algorithm perform both tasks?
Yes. Decision trees, random forests, support vector machines, K-nearest neighbors, and neural networks have variants that support classification and regression.
Can regression predict categories?
Ordinary regression predicts numerical values. A classification system may use numerical scores or probabilities internally, but its final target is still a category.
Which task is easier?
Neither is universally easier. Difficulty depends on data quality, target noise, feature quality, class balance, evaluation requirements, and how stable the underlying relationships are.
Where to Learn Next
Next, learn how labeled examples are separated for model development and final evaluation.