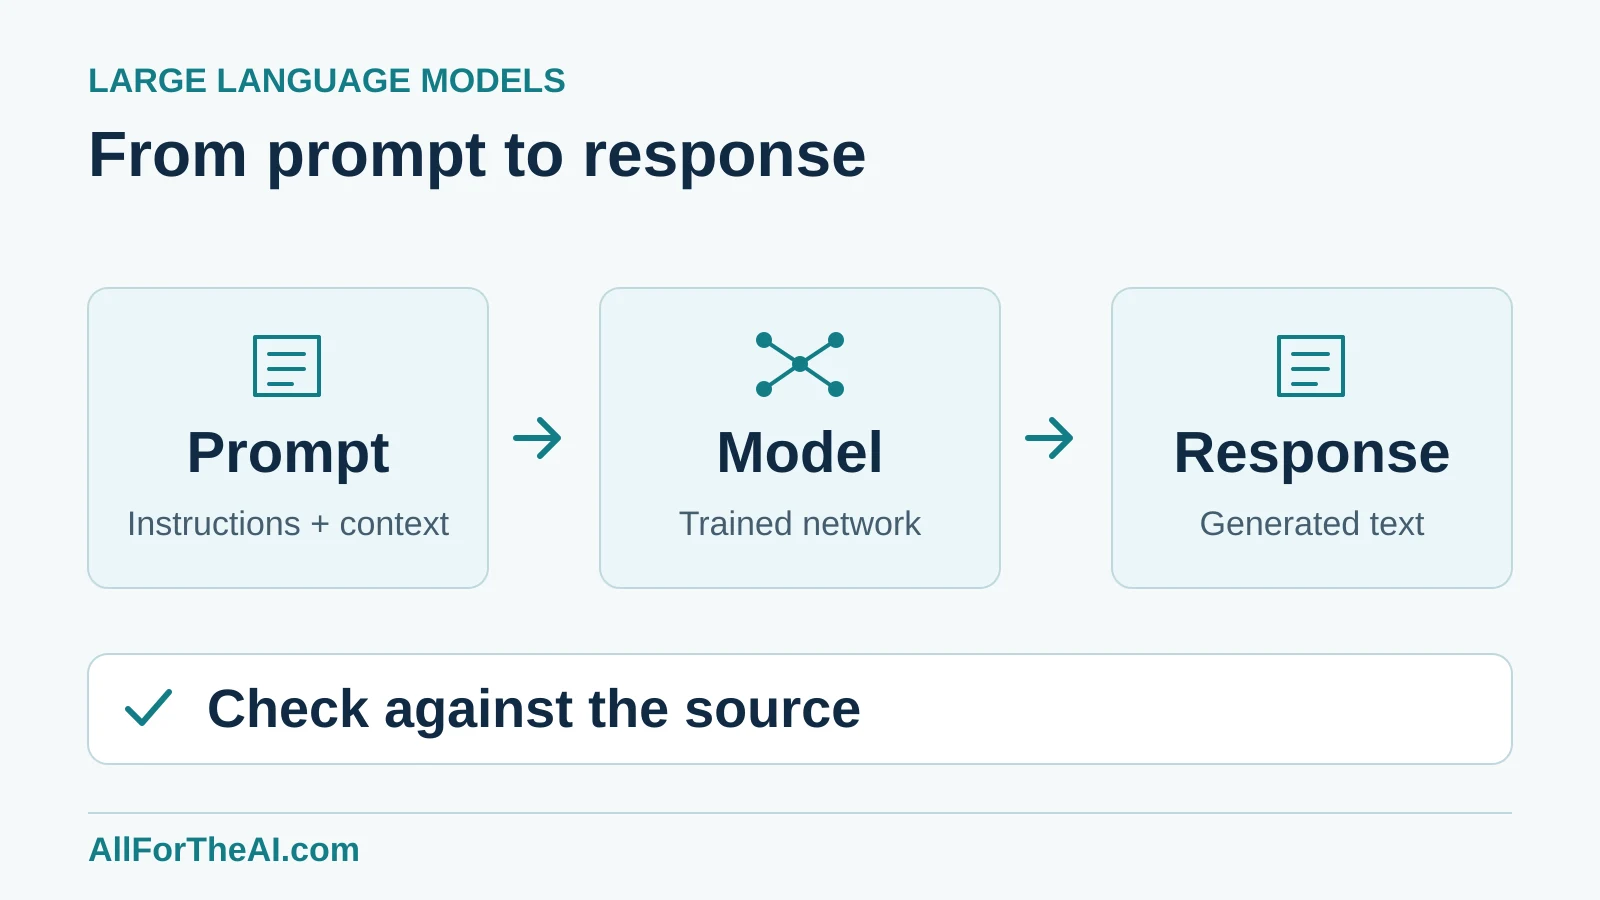
A large language model (LLM) is a neural network trained on substantial amounts of language data to learn patterns it can use in language tasks. Its learned numerical settings are called parameters. “Large” has no single agreed parameter threshold. For the underlying terminology, see Google’s machine-learning glossary.
An LLM can help draft, summarize or answer questions. To use one well, separate three things: what it learned during training, what information it receives now, and what evidence supports its answer.
For the broader category of systems that create text, images and other content, see our Generative AI guide.
This guide follows a fictional garden notice from prompt to useful summary. You will see a sentence grow token by token, then practice checking the result.
What is the difference between an LLM, GPT and a chatbot?
These terms describe different parts of the picture:
| Term | What it describes | Read next |
|---|---|---|
| LLM | A category of language model | This guide explains the category and its use |
| Foundation model | A broadly trained model that can be adapted for multiple tasks; many LLMs fit this description | Foundation Models Explained |
| GPT | A family of generative pretrained Transformer models | GPT Explained |
| Chatbot | An application people converse with; its design may include a model, instructions, retrieval and tools | Chatbots Explained |
The Foundation Models guide explores how an application combines a model with instructions, documents and tools.
Training and inference do different jobs
During training, an optimization process adjusts model parameters. During ordinary inference, the trained model uses its parameters and the current input without updating those parameters.
For an autoregressive text model, pretraining commonly involves predicting the next token across many training examples. A token is a unit from the model’s vocabulary, which may represent a word, part of a word or another text unit. Post-training can then adapt behavior toward tasks such as following instructions. Different models use different recipes. Hugging Face’s architecture guide explains the main model families.
| Stage | What changes? | What it means for the reader |
|---|---|---|
| Pretraining | Learned model parameters | Establishes broad patterns used across tasks |
| Post-training | Parameters or trainable components | Can adapt behavior, such as instruction following |
| Ordinary inference | The input and generated sequence | Produces a response using a trained model |
One influential instruction-tuning study trained on demonstrations, then used human rankings of outputs for further training. The resulting models still made mistakes. That is an example of a training method, not a recipe shared by every LLM. Ouyang and colleagues, 2022.
Adding a notice to a prompt supplies context for the response. It is not, by itself, fine-tuning. Whether an application stores the conversation or later uses it for training is a separate product and policy question.
How does an LLM generate text?
The following simplified loop describes autoregressive text generation, as used by GPT-style models. Language models also include other designs, such as encoders trained to reconstruct masked text; the loop is not a definition of every LLM. Transformer architecture overview.
- Prepare the input. Instructions, the user’s question and any supplied reference text are assembled into the input.
- Represent the text numerically. A tokenizer converts text into token IDs. The model works with numerical representations of those tokens.
- Compute next-token scores. The trained network processes the context and produces scores for possible next tokens.
- Select a token. A decoding strategy uses those scores to choose the next token. It may select the highest-scoring option or sample from a probability distribution.
- Continue or stop. The selected token becomes part of the sequence. Generation repeats until a stopping condition or limit is reached.
This process is described in Hugging Face’s inference guide.
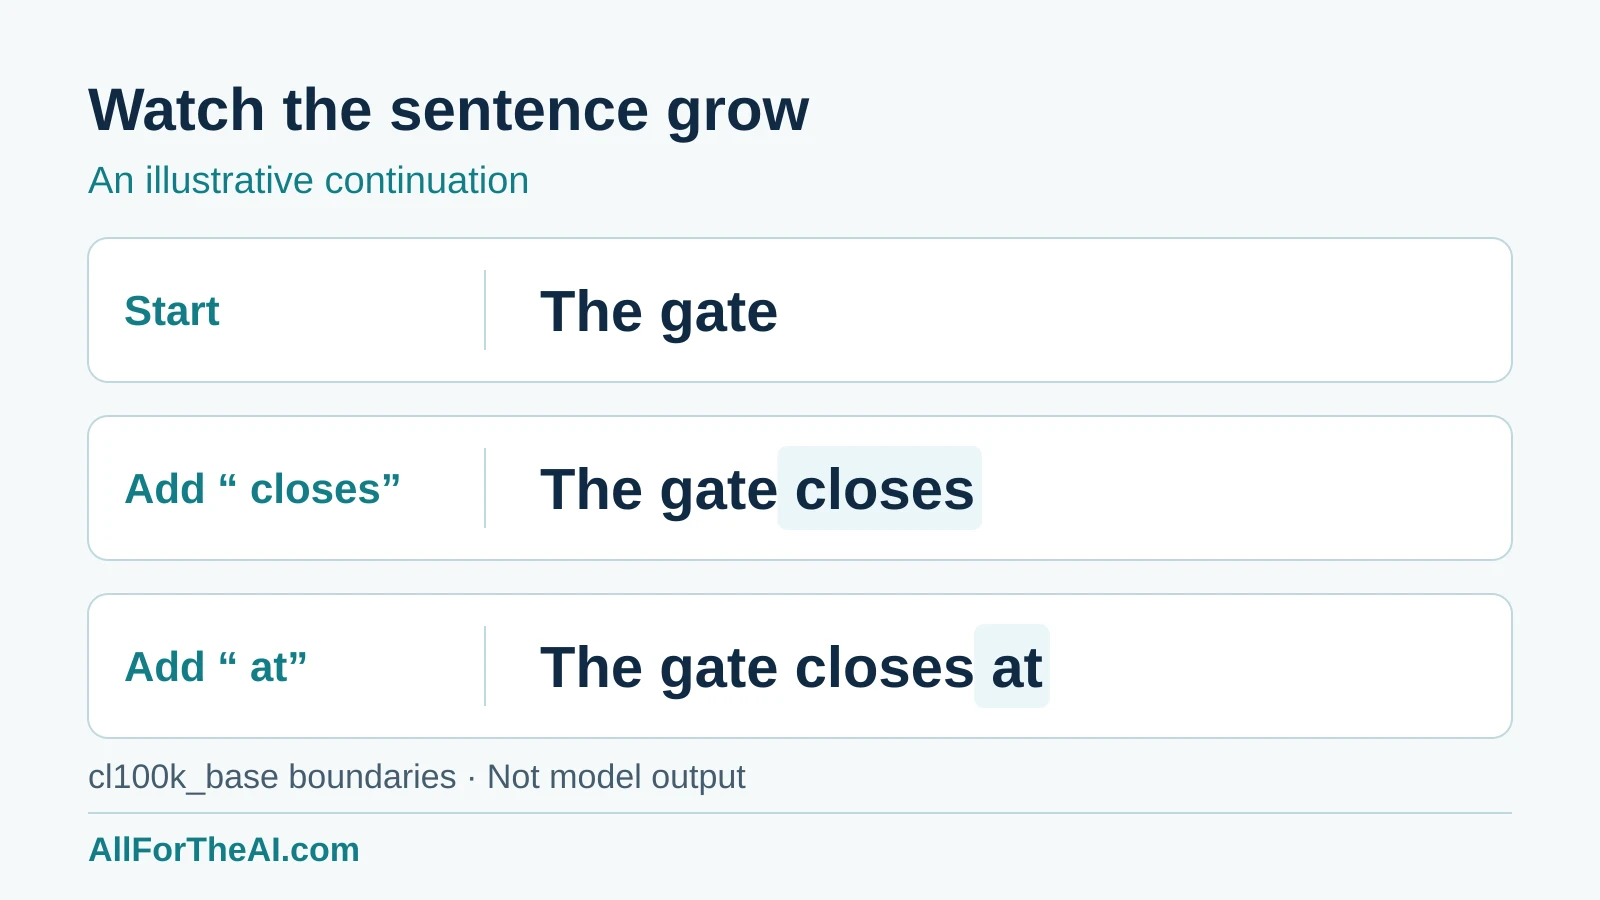
For a concrete illustration, start with “The gate”. Append the token “ closes” to get “The gate closes”, then append “ at” to get “The gate closes at”. The leading spaces are part of those tokens. We verified these token boundaries with the cl100k_base encoding in tiktoken; the chosen continuation is an illustration, not a recorded model prediction. Other tokenizers can divide text differently.
The model’s numerical representations and attention operations let it use relationships within the context. For a closer look at that machinery, see Transformers in NLP. You do not need to calculate attention to check whether an answer matches a source.
A worked example: turn a notice into a useful summary
Imagine this fictional notice is the only source supplied to an assistant:
Oak Lane Garden’s gate closes at 6 pm on Wednesdays. Visitors must leave before the gate closes.
First, ask for a short reminder: “Rewrite this notice as one clear sentence for visitors. Preserve the day, time and departure rule.”
An illustrative successful response is:
On Wednesdays, leave Oak Lane Garden before the gate closes at 6 pm.
This version brings the visitor’s action to the front and combines two sentences into one. It keeps Wednesday, 6 pm and the instruction to leave before closing. That is a useful drafting task with a clear way to judge the result. The sample is written for this explanation; it is not output from a model trial.
For questions about the notice, try this instruction in a model you already use:
Use only the notice below. Answer the question, identify the supporting words, and say when the notice does not provide the requested detail. Do not add opening hours or make assumptions about other days.
Then paste the notice and ask these questions. These are illustrative answers:
| Question | A supported response | What to check |
|---|---|---|
| When does the gate close on Wednesday? | 6 pm | The notice explicitly gives the day and closing time |
| What time does the garden open on Wednesday? | The notice does not give an opening time | Closing time does not establish opening time |
| Does it also close at 6 pm on Thursday? | The notice does not say | A statement about Wednesday does not establish Thursday’s hours |
Now consider this proposed summary:
The garden is open every day until 6 pm, and visitors may stay after the gate closes.
It has two different problems. “Every day” adds an unsupported schedule. “Visitors may stay” contradicts the notice. A fluent sentence can contain both an invention and a contradiction.
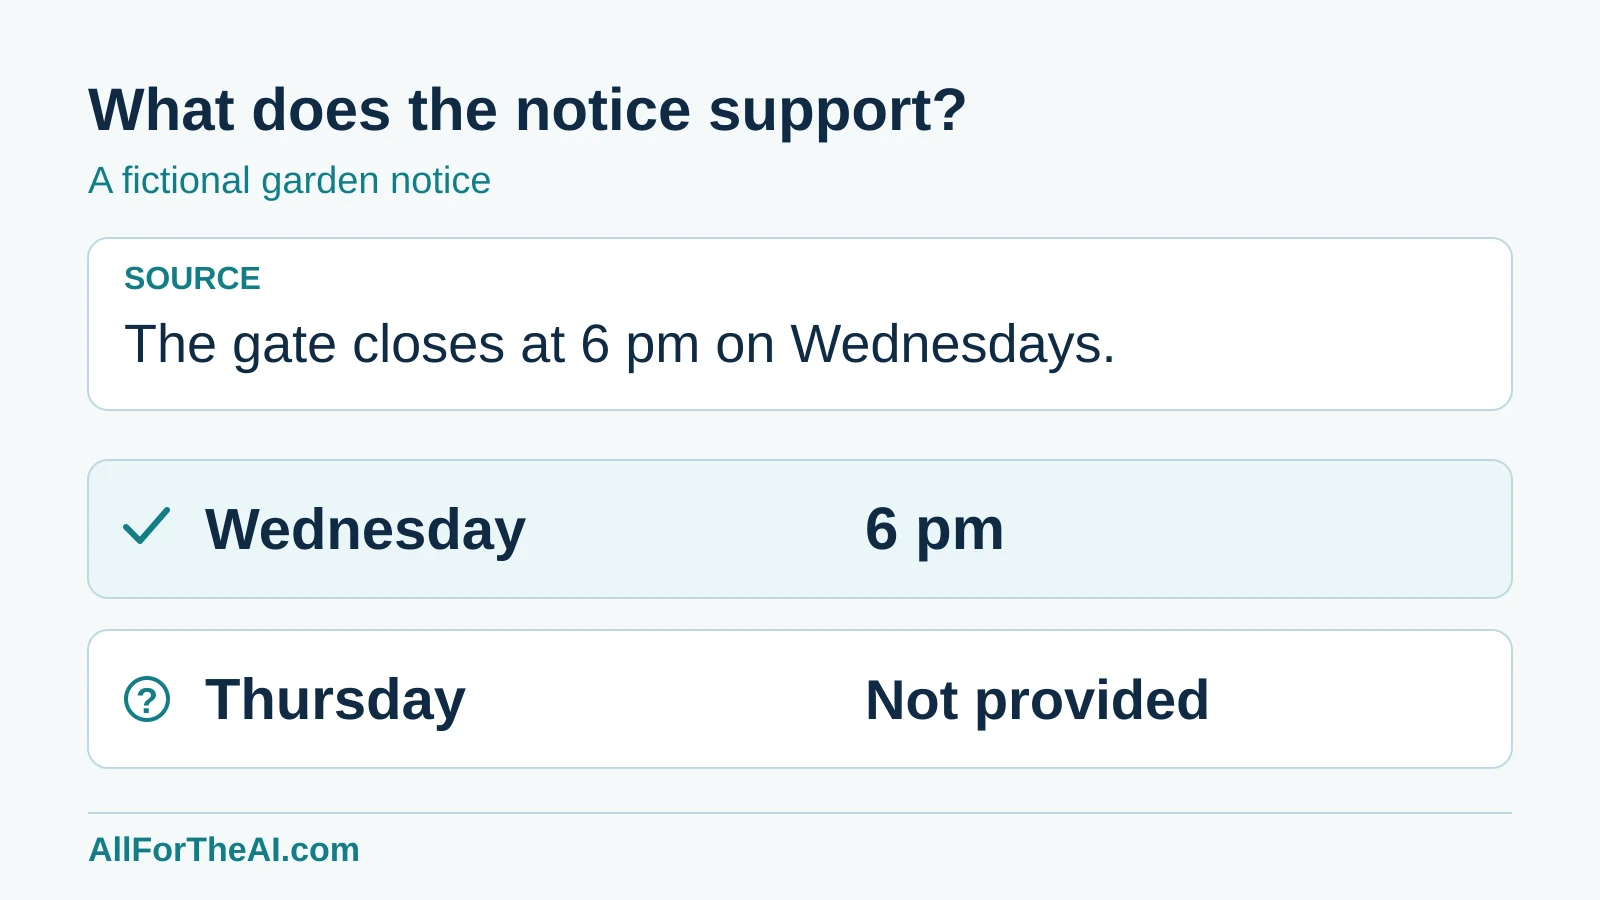
When reviewing a response, distinguish supported claims, missing information and contradictions. NIST identifies confidently false claims, contradictions and fabricated citations as generative-AI risks and recommends verifying output sources. NIST Generative AI Profile, sections 2.2 and 3.
What is a context window?
The context window limits how many tokens a model can handle in a request and its generated continuation, subject to the model and service’s particular limits. Long documents, conversation history and requested output all compete for that capacity. Tokens do not correspond to a fixed number of words. Hugging Face’s tokenization guide explains why tokenization varies.
Fitting a document into the available context does not establish that every relevant detail will be used correctly. The 2023 Lost in the Middle study found that answer quality depended on where relevant information appeared in the context for the models and tasks it tested. Those results are not a scorecard for every current model. Liu and colleagues.
For longer documents, preserve section names and ask for the relevant passage alongside the answer.
What can you use an LLM for?
Start with tasks whose results you can review. These are suggested workflows, not measured performance claims:
| Task | Example | A useful review criterion |
|---|---|---|
| Summarizing | Turn a notice into three bullets | All original conditions remain intact |
| Drafting | Write a clearer version of an announcement | No new facts or promises are added |
| Extracting | Return the named day and closing time in a table | Every field matches the source, or is marked missing |
| Explaining | Describe a technical term for a beginner | The explanation survives comparison with a reliable reference |
Set the review criterion before generating the answer. “Sounds professional” is not enough when the task is to preserve facts.
Prompting, retrieval or fine-tuning: which changes what?
Prompting supplies instructions, examples and context for a request. For our notice, that might be “use only this source” plus the text itself.
Retrieval-augmented generation (RAG) adds a process for finding reference material and supplying it to a generator. The original RAG research combined a retriever, an external document index and a pretrained generator. In use, retrieving a passage does not itself update the generator’s weights. The original research also trained components of its system; retrieval and training are distinct operations. Lewis and colleagues, 2020.
Fine-tuning uses additional training to adjust a model or trainable components. It can target behavior, but it does not replace checking whether an answer matches a changing source. These approaches can be combined in one application.
An application needs an appropriate connection to retrieve current notices. The model’s name alone does not establish access to live web pages or private documents.
A checklist before you use the answer
- What task did I ask the model to do?
- Which source should establish the facts?
- Does each factual claim match that source?
- Did the answer preserve dates, conditions and exceptions?
- Did it acknowledge information the source does not provide?
- Is a person with the relevant expertise needed before I act?
The garden example gives you a reusable pattern: supply a source, define the transformation you need, and review the result against specific criteria.
Where to Learn Next
See how text becomes the units a language model processes.
For the wider picture, read Foundation Models Explained. To learn how an application brings reference material into a response, continue with Retrieval-Augmented Generation Explained.