Imbalanced Datasets Explained
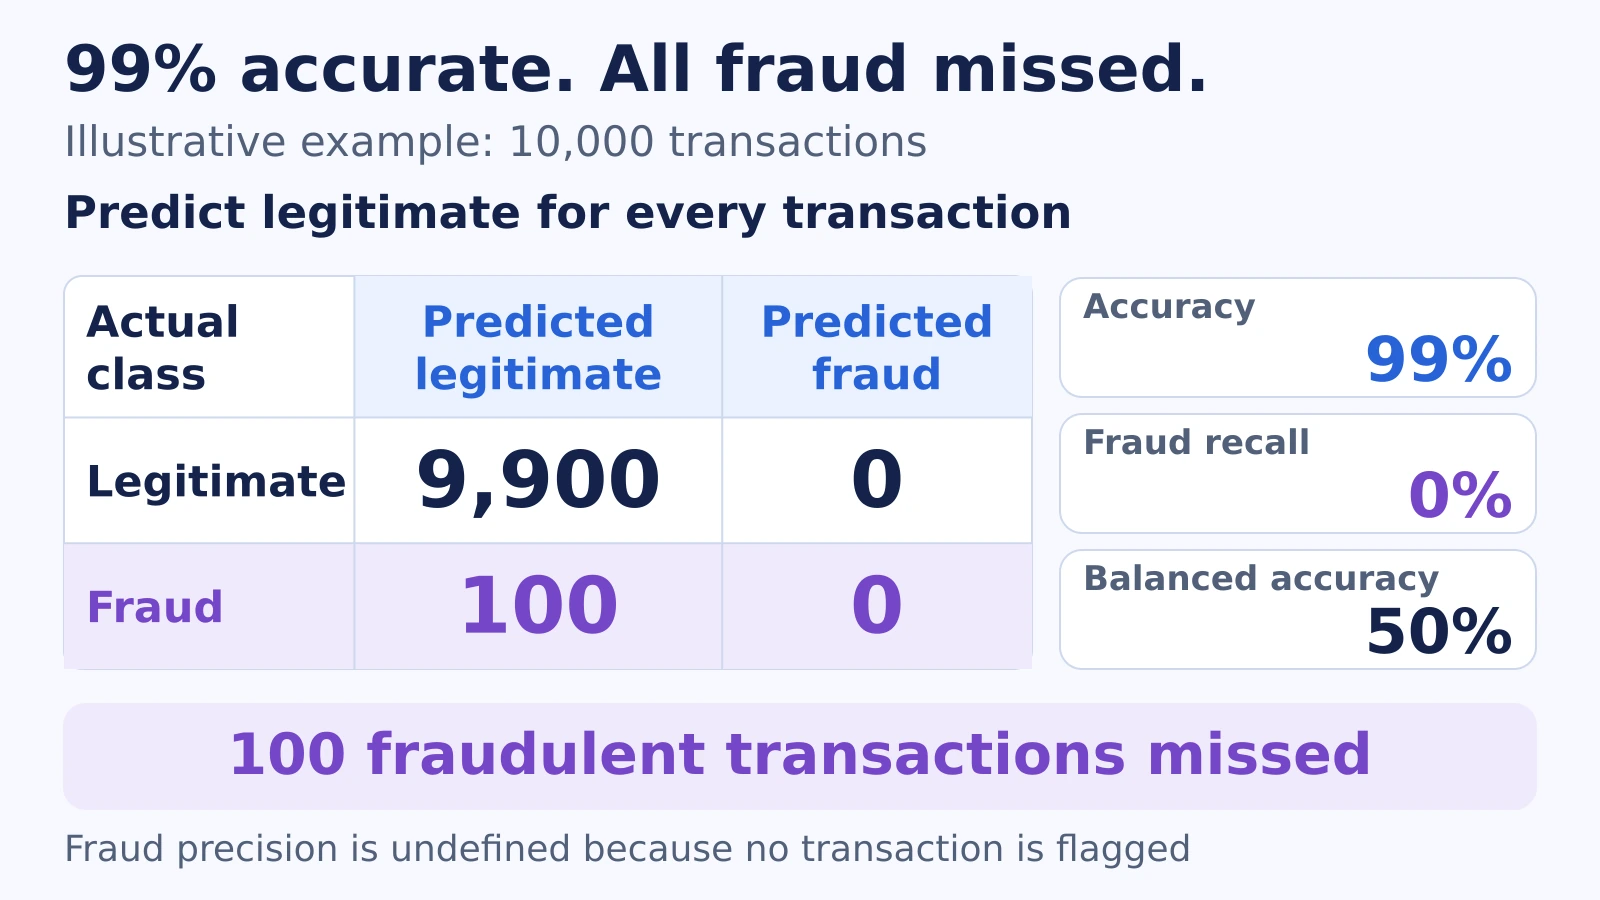
Understand class imbalance, evaluate rare outcomes, compare weighting and sampling, and protect validation and test data from leakage.
Imbalanced Datasets Explained Read More »
Learn how data powers AI and machine learning, from datasets and data quality to preprocessing, training and testing splits, and feature engineering.
New to the topic? Start with What Is a Dataset in Machine Learning? →
Understand class imbalance, evaluate rare outcomes, compare weighting and sampling, and protect validation and test data from leakage.
Imbalanced Datasets Explained Read More »
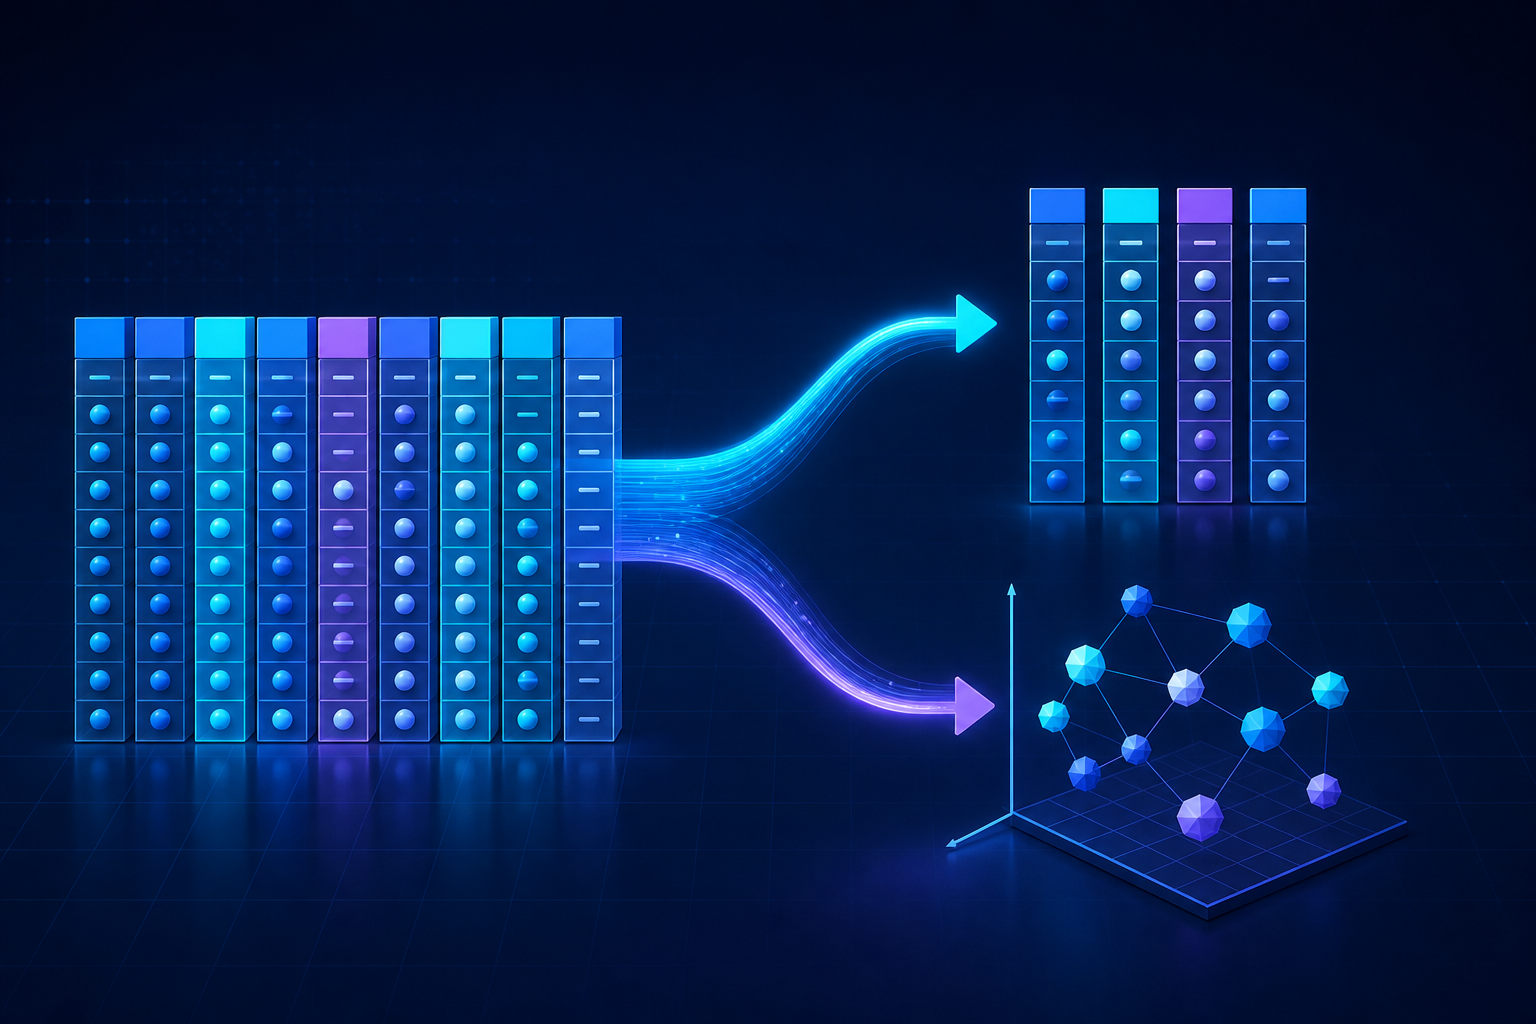
Feature selection keeps a useful subset of the original inputs. Feature extraction transforms inputs into a new representation. Both can reduce complexity, but neither automatically improves a model. The right choice must be tested with a leakage-safe validation process. Published April 30, 2026 · Reviewed and updated August 27, 2026 This lesson builds on Feature
Feature Selection vs Feature Extraction Explained Read More »
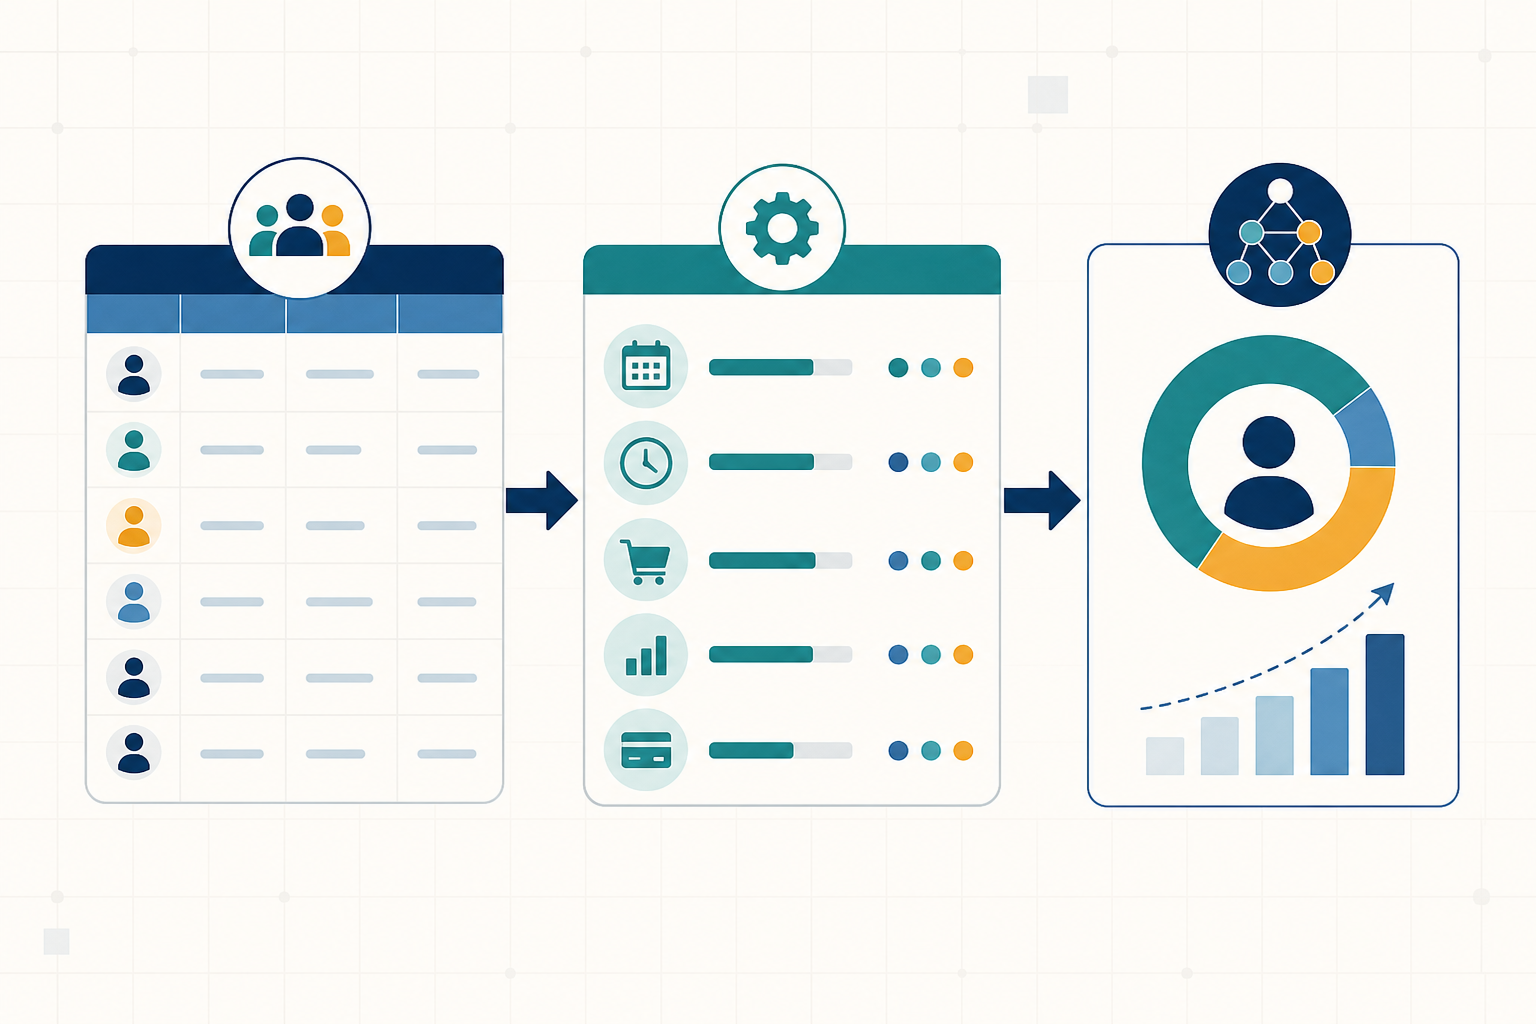
Updated August 27, 2026 Feature engineering turns available or prepared data into useful inputs that help a machine learning model recognize patterns. It is the step where you decide what information the model should learn from—and how that information should be represented. This lesson follows Data Preprocessing Explained. If you are new to training, validation,
Feature Engineering Explained Read More »
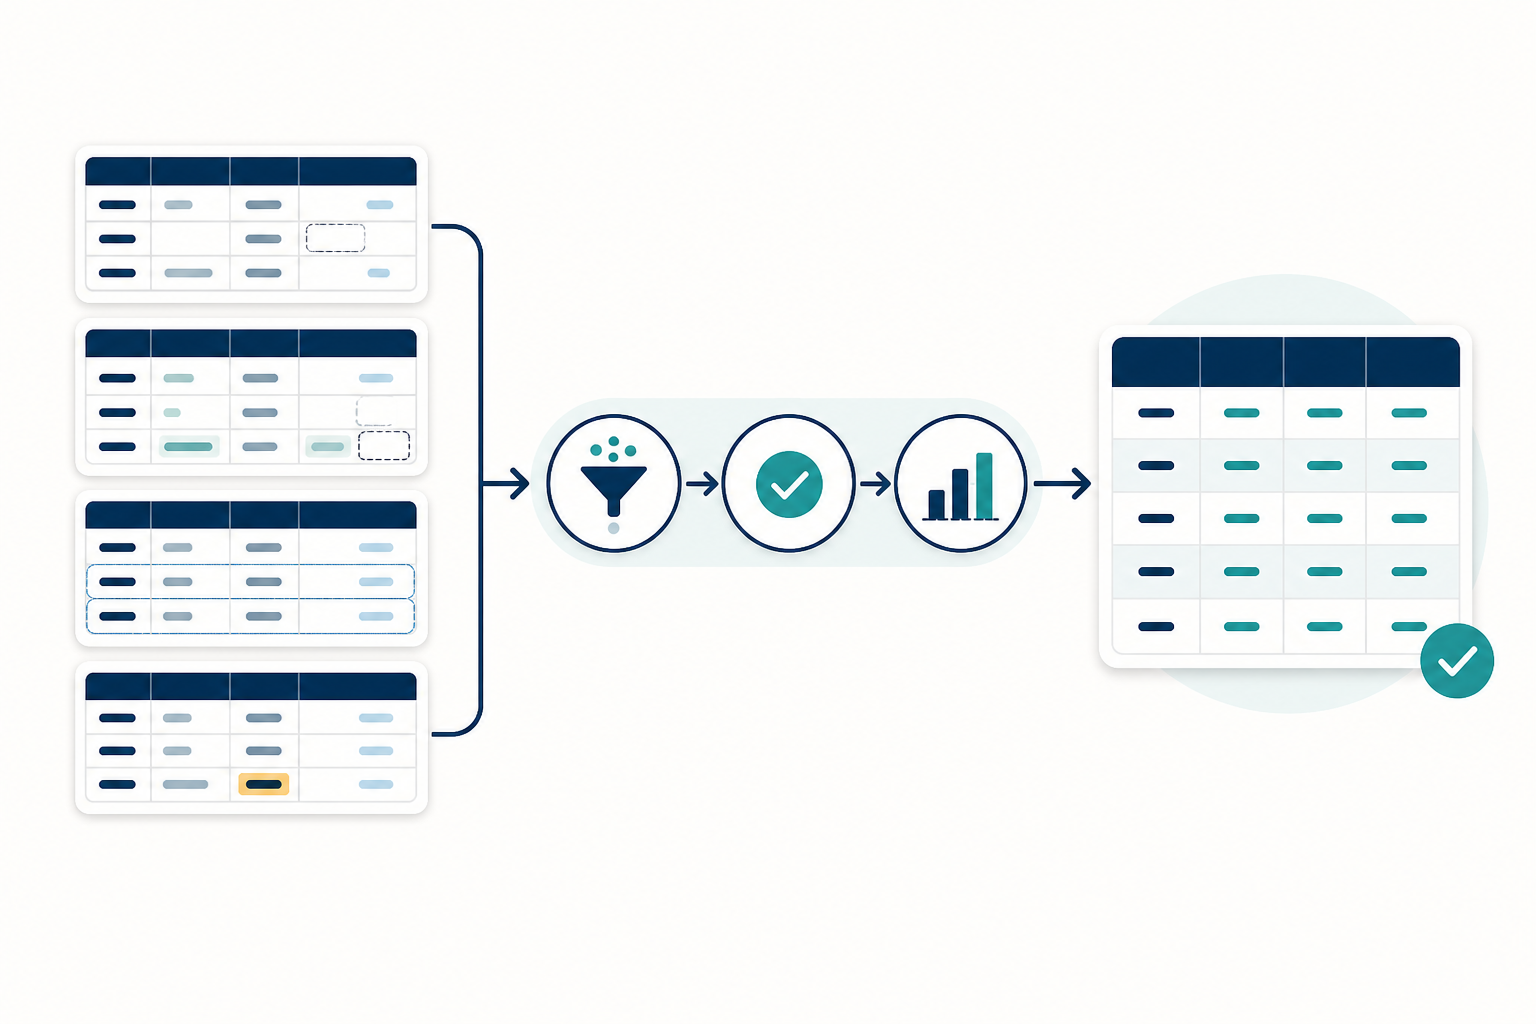
Last reviewed and updated: August 27, 2026 Data preprocessing is the process of checking, cleaning, transforming, and organizing raw data so it can be used reliably by a machine-learning system. The goal is not to make data look perfect. It is to create inputs that match the model, evaluation plan, and real-world prediction task. Preprocessing
Data Preprocessing Explained Read More »
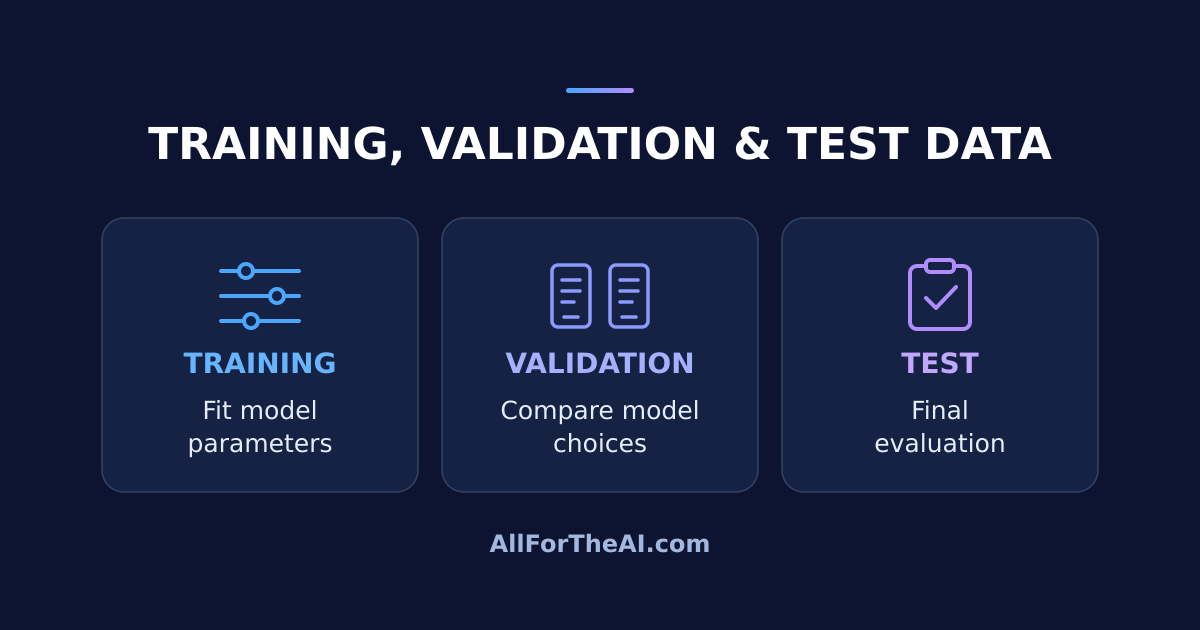
Last reviewed and updated: September 1, 2026 Training, validation, and test data are separate data subsets or collections, and each has a different job. Training data teaches the model, validation data guides development choices, and test data provides a final check on unseen examples. Keeping these roles separate helps produce a more honest estimate of
Training vs Testing Data in Machine Learning Read More »
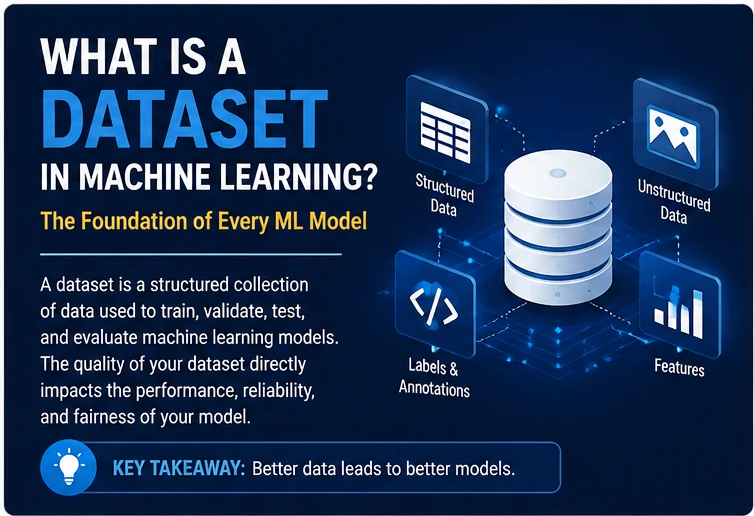
Last updated: September 30, 2026 A dataset is a collection of examples used to develop, evaluate, or operate a machine-learning system. Depending on the task, each example may contain features, labels, text, images, audio, sensor readings, transactions, or other information. The Google Machine Learning Glossary provides useful reference definitions for examples, features, labels, training sets,
What Is a Dataset in Machine Learning? Read More »