Word Embeddings in Simple Terms
Word embeddings are numerical vector representations that capture useful statistical relationships between words or tokens. Language units that occur in related contexts can develop similar positions in a learned vector space, allowing models to compare and process language mathematically. This does not mean the model understands meaning as a person does.
What Are Word Embeddings?
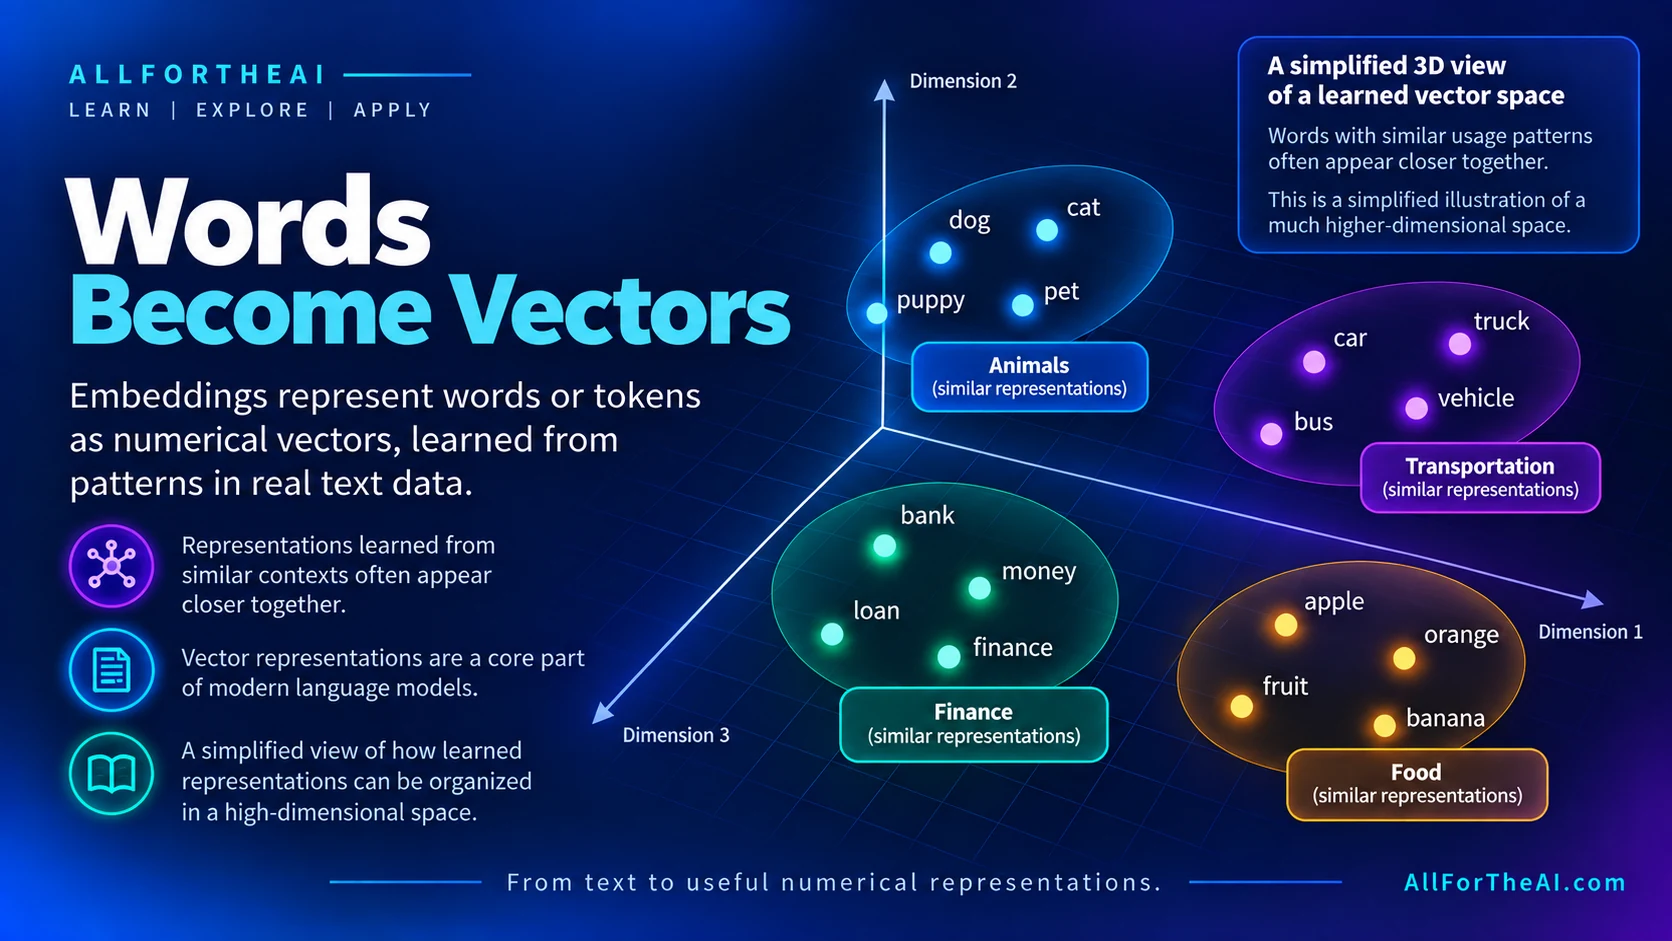
Computers operate on numbers rather than raw text. An embedding maps a language unit to a dense vector: an ordered list of values such as [0.42, 0.15, −0.67, …]. A training objective adjusts those values so that useful linguistic patterns emerge in the geometry.
The familiar “language map” analogy is useful, but it has limits. Nearby vectors may reflect similarity, association, syntax, topic, or another pattern in the training data. A vector is not a dictionary definition, and distance is not a perfect measure of human meaning.
Words, Tokens, and Subwords
Traditional systems such as Word2Vec and GloVe generally assign one vector to each word in a vocabulary. Modern language models usually work with tokens, which may be complete words, parts of words, punctuation, or other text pieces. Therefore, modern models often use token embeddings rather than strictly word embeddings.
Subword tokenization helps a model represent unfamiliar or rare words by breaking them into known pieces. Token boundaries depend on the tokenizer, so one written word does not always equal one token.
Why Dense Embeddings Replaced One-Hot Vectors
A one-hot vector assigns each vocabulary item a separate position. For example, cat might be [1,0,0], dog [0,1,0], and car [0,0,1]. The one-hot vectors themselves do not encode whether two words are semantically related: cat is mathematically just as separate from dog as it is from car. A downstream model can still learn relationships, but the one-hot representation does not supply them.
Dense embeddings use fewer dimensions and learn values from data. This can reduce sparsity and give models useful starting representations for classification, retrieval, translation, generation, and other NLP tasks.
How Embeddings Learn Useful Geometry

Embedding methods learn from text by optimizing a defined objective. Some predict a word from nearby context; others use corpus-wide co-occurrence counts. During training, the objective adjusts vector values so words or tokens used in related contexts can develop useful geometric relationships.
Similarity is often estimated with a measure such as cosine similarity. The result depends on the model, training objective, corpus, and vocabulary. Related items such as doctor and nurse may be close because they appear in similar topics and contexts, even though they are not synonyms.
The Famous King–Queen Analogy
king − man + woman ≈ queen is a well-known illustration of linear regularities that can appear in some learned vector spaces. It does not work reliably for every relationship, prove that the model has stored complete concepts, or show human-like understanding. It demonstrates that statistical training can produce useful geometric structure.
Static Word Embeddings: Word2Vec, GloVe, and FastText
Word2Vec
Word2Vec is a family of efficient techniques introduced by researchers at Google. Its skip-gram and continuous bag-of-words objectives learn static word vectors from local context prediction. Each vocabulary word normally receives one vector, regardless of the sentence in which it appears.
GloVe
GloVe, developed at Stanford, learns static word vectors from global word–word co-occurrence statistics. The practical distinction is method: Word2Vec learns primarily through local context-prediction objectives, while GloVe explicitly uses aggregate co-occurrence information from the corpus.
FastText
FastText represents a word using character n-grams in addition to the whole word. This subword structure can help construct representations for rare or previously unseen words and can capture patterns shared by related word forms. It is different from the learned subword token embeddings used inside many modern Transformers, although both make use of smaller-than-word units.
From Static Embeddings to Contextual Representations
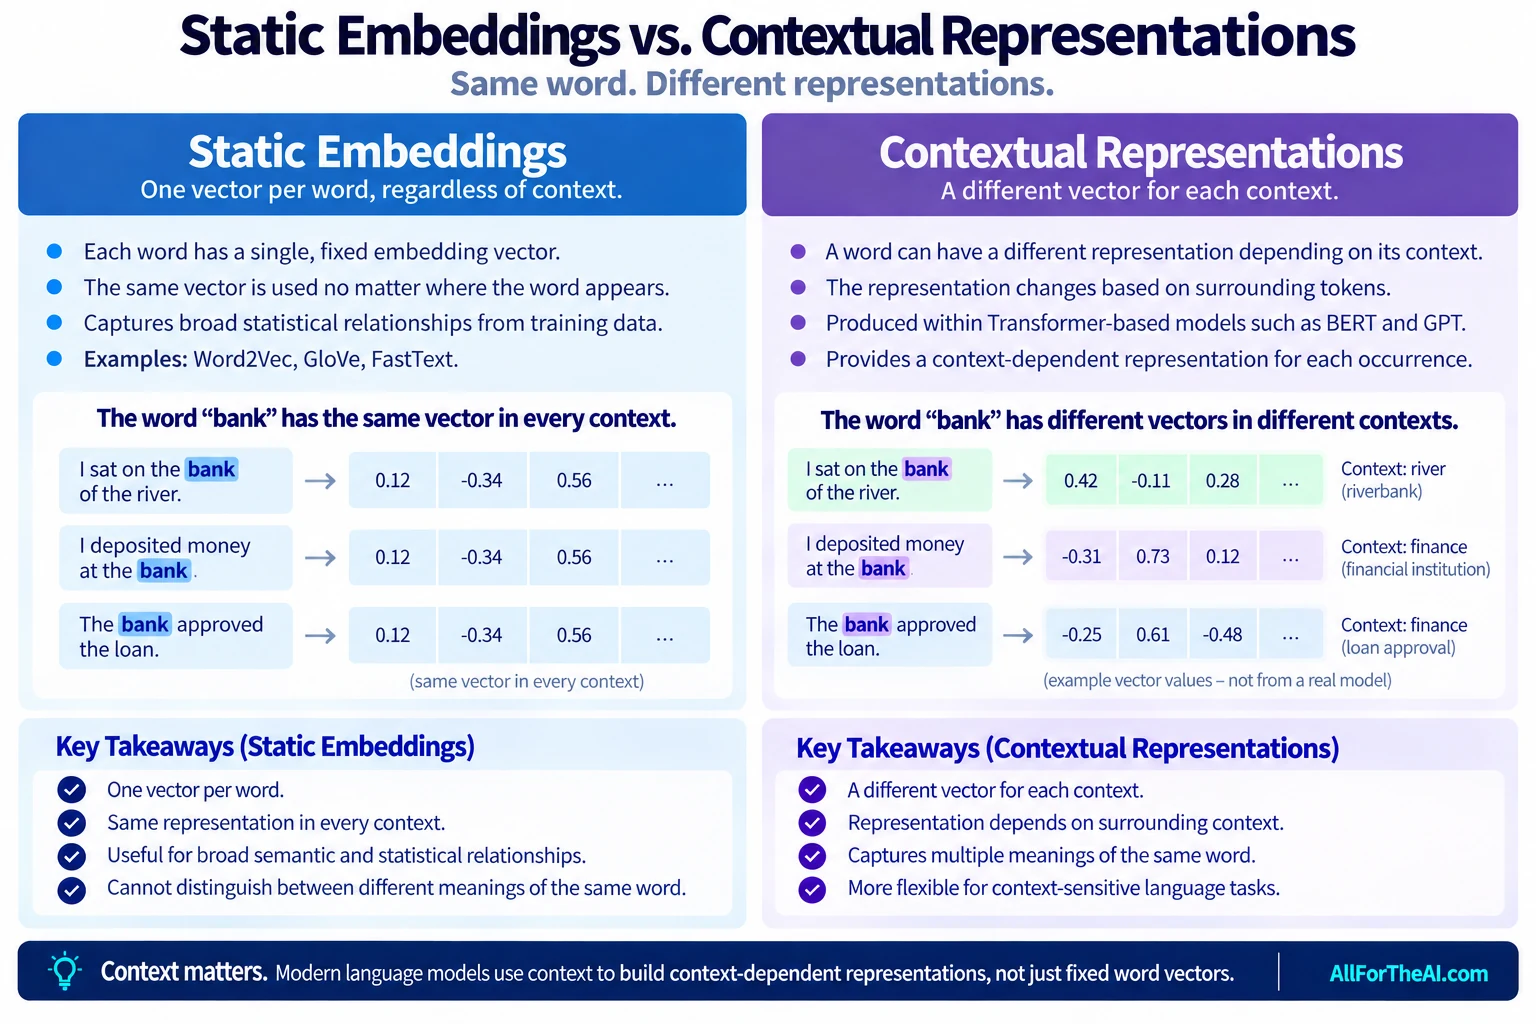
A static embedding gives a word such as bank the same vector in “bank account” and “river bank.” Transformer-based models handle context differently. They begin with token embeddings, then repeatedly transform those representations as information moves through attention and other neural-network layers.
BERT and GPT are Transformer-based language-model architectures, not embedding methods equivalent to Word2Vec or GloVe. They contain embedding layers and produce context-dependent hidden representations. In BERT, for example, the representation of bank can differ between the financial and river sentences because surrounding tokens influence it.
| Concept | Static word embedding | Contextual representation |
|---|---|---|
| Examples | Word2Vec, GloVe, FastText | Hidden states produced by BERT or other Transformers |
| Changes with sentence context? | No | Yes |
| Same word or token gets the same vector every time? | Usually yes | The initial token embedding may be fixed; later hidden representations change |
| Handles multiple senses? | Limited | Usually much better |
How Embeddings Fit Into Modern Language Models
A useful high-level sequence for a Transformer language model is:
- Text: the user supplies a prompt.
- Tokens: a tokenizer splits the text into model-specific units that may not match whole words.
- Initial token embeddings: the model maps each token ID to a learned vector and combines it with position information.
- Transformer context processing: attention and neural-network layers build context-sensitive hidden representations.
- Generated tokens: the model predicts a distribution for the next token, selects one, and repeats the process.
The initial embedding does not already contain the complete contextual interpretation of the prompt. Context-dependent information develops through the Transformer layers. Read Transformers in NLP for the next step in this learning path.
Embedding Models vs Token Embeddings vs Hidden Representations
| Term | What it means | Typical use |
|---|---|---|
| Embedding model | A model designed to convert content such as a sentence or document into a vector | Semantic search, clustering, retrieval, recommendations, and RAG |
| Token embedding | The initial learned vector associated with a token ID inside a language model | Input to Transformer processing |
| Contextual hidden representation | A transformed, context-dependent vector produced within later model layers | Context-sensitive language processing and generation computations inside the model |
These ideas are related but not interchangeable. A sentence-level embedding returned for semantic search is not the same thing as an individual token embedding inside an LLM, and neither is identical to a deeper contextual hidden state.
Where Embeddings Are Used
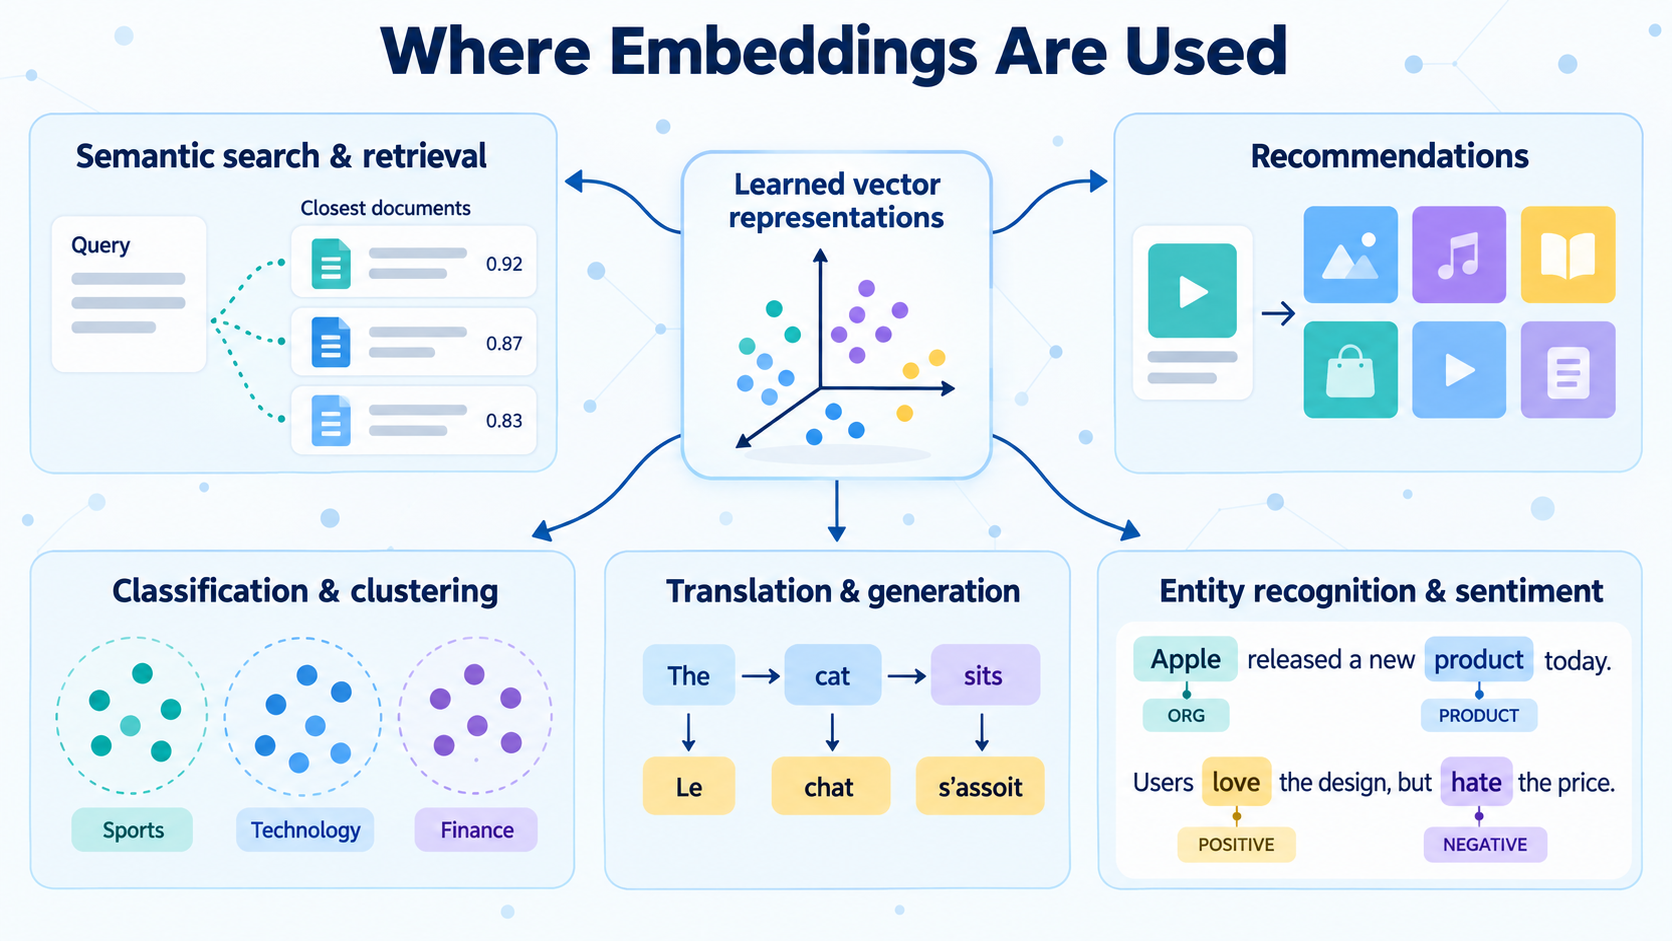
- Semantic search and retrieval: compare a query vector with document vectors to find related content.
- Clustering and classification: group or label text using learned numerical features.
- Recommendation: compare representations of users, items, or content as one component of a larger system.
- Translation and generation: provide numerical inputs that neural language models process in context.
- Named entity recognition and sentiment analysis: provide features used with other model components for task-specific predictions.
Real production systems combine embeddings with training objectives, ranking logic, databases, neural networks, and other components. It is safer to say embeddings can be an important component than to attribute an entire product’s behavior to embeddings alone.
Limitations, Bias, and Interpretation
- Data dependence: the geometry reflects patterns in the training corpus and the chosen learning objective.
- Bias: historical and social biases in data can appear in an embedding space and affect downstream results.
- Similarity is ambiguous: closeness may indicate topic, association, syntax, usage, or another learned property—not necessarily synonymy.
- Static context limits: one fixed vector cannot cleanly represent every sense of a polysemous word.
- Interpretability: individual dimensions rarely correspond to simple human-readable properties.
- No human-like understanding: a vector encodes patterns useful to computation; it is not a definition, belief, or conscious concept.
Frequently Asked Questions
What is a word embedding in simple terms?
It is a numerical vector learned from language data. The vector’s relationships to other vectors can help a model compare and process words mathematically.
Are words and tokens the same?
Not always. A token can be a whole word, part of a word, punctuation, or another text unit. Modern language models commonly embed tokens rather than written words directly.
Are BERT and GPT embedding methods?
No. They are Transformer-based language-model architectures. They use embedding layers and produce contextual hidden representations, but they are not static embedding techniques comparable to Word2Vec or GloVe.
Do embeddings contain meaning?
They can encode statistical structure that correlates with semantic and syntactic relationships. Saying they “contain meaning” is useful shorthand, but it should not be confused with a dictionary definition or human understanding.
Primary Sources and Further Reading
- Mikolov et al., Efficient Estimation of Word Representations in Vector Space (Word2Vec)
- Pennington, Socher, and Manning, GloVe: Global Vectors for Word Representation
- Bojanowski et al., Enriching Word Vectors with Subword Information (FastText)
- Devlin et al., BERT: Pre-training of Deep Bidirectional Transformers for Language Understanding
- Vaswani et al., Attention Is All You Need
Continue the NLP Learning Path
If tokenization is the prerequisite and embeddings provide numerical representations, the logical next lesson is how Transformer models process those representations in context.
Next lesson: Transformers in NLP
Related branches: Named Entity Recognition, Text Classification, and Sentiment Analysis.